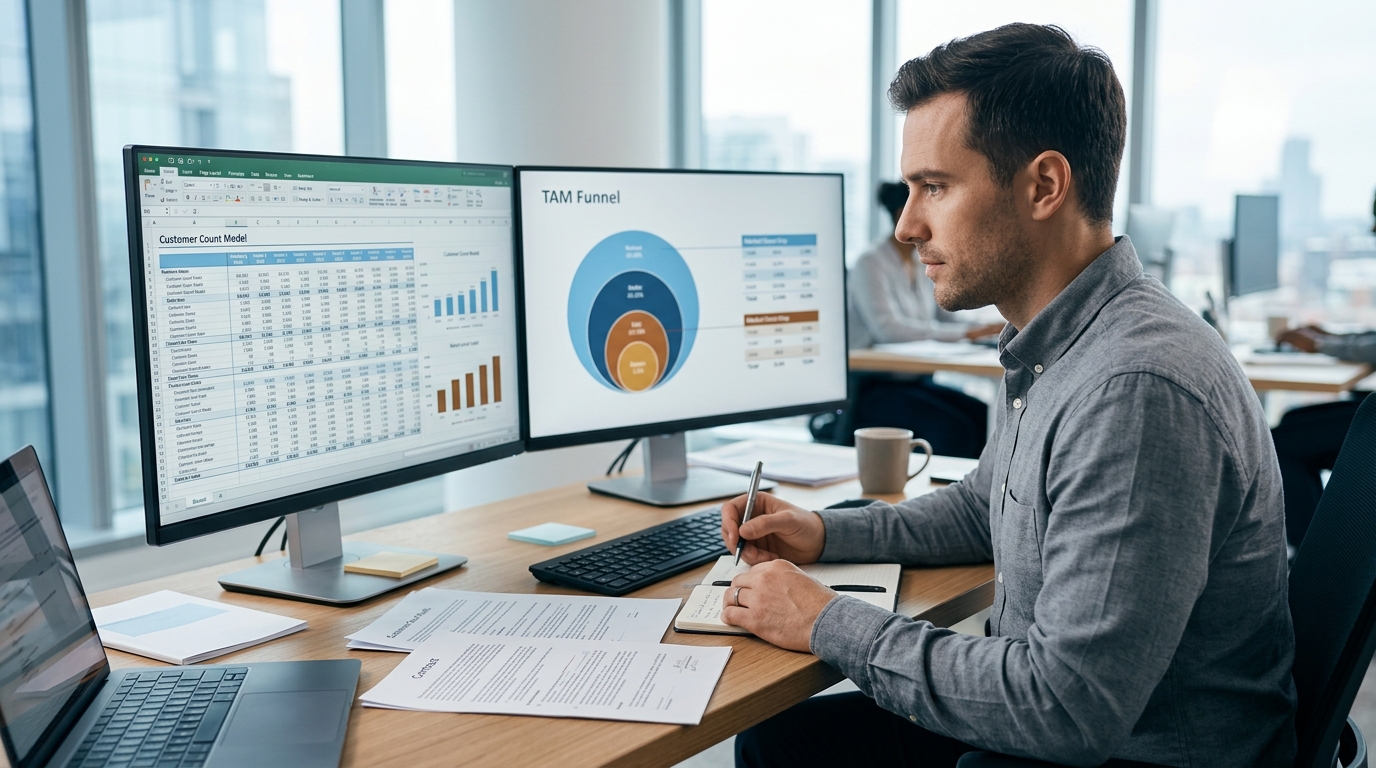
What bottom-up market assessment means in PE diligence
Bottom-up market assessment sizes a target's niche from verifiable units rather than from an extrapolated analyst figure. The deal team counts the actual customer segments a target can serve, triangulates the revenue it can earn per customer from contracts, pricing files and comparable transactions, and multiplies the two to build a total addressable market. Every input is a document or a registry entry that can be inspected, so the resulting number can be defended line by line in front of an investment committee. In commercial diligence this is the difference between a market size that is asserted and one that is evidenced.
The contrast with top-down sizing is mechanical. Top-down starts with an industry-level figure, often from a syndicated report, and narrows it to the target's slice using assumed percentages. It is fast, and it works when the segment is well covered. Bottom-up starts at the customer level and scales up. As Carta's market sizing guidance notes, top-down is quicker but less accurate because it relies on estimates, while bottom-up is more time-consuming but typically produces more accurate results. For a niche below the coverage threshold of the major research houses, there is often no credible top-down figure to start from, which forces the bottom-up build.
| Dimension | Top-down | Bottom-up |
|---|---|---|
| Starting point | Industry-level report figure | Countable customer units and pricing evidence |
| Key inputs | Published market total, narrowing percentages | Registry counts, contracts, pricing files, CRM exports |
| Speed | Fast, often same-week | Slower, requires document work and primary checks |
| Accuracy in niches | Degrades where reports do not cover the segment | Holds up, because each input is verifiable |
| IC scrutiny | Vulnerable to challenge on source coverage | Defensible when sources are cited per input |
A decision-grade sizing output for an investment committee has four properties, and a structured market sizing workstream is usually judged against them:
- A clearly defined solution scope, stating which products, use cases, buyer types and geographies are counted and which are excluded.
- Unit counts for each customer segment, each traced to a named source such as a business registry, NACE code table or trade-association statistic.
- A revenue-per-customer figure triangulated from at least three independent sources, with the spread disclosed.
- An explicit reconciliation against the target's actual revenue, showing the implied market share and whether that share is plausible.
Why niche markets demand source-grounded sizing
The competitive context raises the bar. Private equity and venture capital dry powder has receded from its all-time highs after an extended fundraising slowdown, yet the pool of uncommitted capital waiting to be deployed remains very large. Deal activity has moved with it, with later-stage investments and middle market transactions adding to large-scale buyout momentum. When that much capital competes for assets, the attractive niches are the ones no report covers, and the teams that can size them credibly move faster.
Fragmentation is structural, not incidental. In 2022 the EU had 32.3 million enterprises employing 160 million persons, and 99% of them were micro and small enterprises employing up to 49 persons. A niche serving those businesses is therefore a census problem, not a report problem: the market exists as hundreds of thousands of small buyers, each countable in a registry, and no syndicated study will ever segment it at that resolution. This is the reality for most VC and PE funds working below the mega-deal tier.
Investment committees have adapted. A top-down slide that cites a report covering an adjacent category, then applies a narrowing percentage to reach the target's segment, is increasingly challenged on exactly two points: does the source actually cover this segment, and is each narrowing assumption evidenced? When neither can be answered, the sizing is treated as marketing rather than analysis, and the memo absorbs the hit to credibility.
- Source coverage: does the cited report name the target's segment, or only its parent category?
- Assumption chain: is every narrowing percentage tied to evidence, or carried by assertion?
- Reconciliation: does the implied market share match the target's actual revenue, or does it flatter the thesis?
The bottom-up sizing framework: TAM, SAM, SOM from units
The build starts before any counting, with the scope definition. As commercial diligence practitioners note, a common failure is choosing a broad proxy for the solution area in the name of convenience; the model needs to lock in which SKUs, use cases, buyer types and geographies are included before stakeholders can interpret the numbers. Only then does the unit work begin.
Counting customer segments from registries and trade data
Customer-segment counting draws on three source families. Business registries and national statistics offices provide enterprise counts by industry classification; NACE codes in Europe (and equivalents elsewhere) let the team isolate the verticals the target actually serves. Trade associations publish member directories and sector statistics that often segment more finely than official statistics. Filtering the registry counts by the criteria that define a real buyer, such as company size, geography and the presence of the problem the target solves, converts a raw industry total into a countable potential customer base.
Triangulating revenue per customer
Revenue per customer is the second multiplier, and Carta's framework states it directly: TAM equals the total number of potential customers multiplied by the average annual contract value per customer. The average itself should be triangulated, not asserted. Customer contracts and pricing files from the data room give realized pricing; CRM exports give the distribution, not just the mean, which matters because a few large accounts can distort an average; comparable transactions and competitor rate cards bound the range. Where the three sources disagree, the spread is disclosed rather than averaged away.
The hybrid approach used in commercial diligence treats triangulation as the standard, not the exception: combining published data, top-down checks and bottom-up builds from multiple validated sources is described as the most reliable method for producing a market model an investment committee can act on. The bottom-up build is the spine of that triangulation, because it is the leg whose every input can be re-verified.
Competitor mapping in fragmented markets
When no named-analyst coverage exists, there is no published market-share table to cite, so the team builds a competitor census instead. The method is unglamorous: enumerate the players from business registries, industry directories, trade-association membership lists and the target's own win-loss records, then classify each by segment, geography and estimated scale. The census will not produce a precise share for every player, but it establishes the two facts that matter for the thesis: how many credible competitors exist, and how large the largest of them is relative to the counted market.
Share and consolidation headroom can then be estimated with the sector enterprise count as the denominator. Eurostat's structural business statistics provide exactly this: enterprise counts by industry and size class, so a team can state, for example, that a niche of a few thousand addressable enterprises contains a handful of players above a given revenue scale, and quantify how much of the market remains sub-scale. That headroom number is the raw material of a roll-up thesis, and it belongs in the target screening and IC material from the first pass, not as an afterthought.
Roll-up and add-on theses also carry constraints that a census alone will not surface. As BLG's analysis of private equity consolidation strategies notes, firms need a comprehensive understanding of statutory and regulatory rules that may restrict the ownership or operation of businesses before deploying a roll-up, since ownership restrictions in some industries can force management-agreement or joint-venture structures that make the strategy less economically feasible. The same analysis flags founder retention and earn-out dynamics as recurring execution risks in serial acquisition strategies.
- Regulatory ownership limits that can block a conventional equity roll-up and force alternative structures.
- Industry-specific financial covenants that acquisition debt may need to satisfy.
- Founder and key-person dependencies that concentrate execution risk across multiple simultaneous integrations.
- Exit-market depth, since a consolidator that shrinks the pool of remaining buyers also narrows its own exit options.
What to test: evidence checklist and red flags
The verification layer is where a bottom-up build earns its credibility. The evidence base should be assembled before the model is finalized, and every input should map to a document a committee member could request and receive.
- Customer contracts and pricing files, establishing realized revenue per customer rather than list price.
- CRM exports, showing the customer distribution, concentration and win rates behind the average.
- Registry counts and NACE-code extracts, supporting the customer-segment denominators.
- Trade-association statistics, providing an independent second count for the same segments.
- Competitor census working papers, with the enumeration source for every named player.
Two tests do most of the work. First, reconcile the bottom-up TAM against the target's actual revenue: if the target's current revenue implies a share of the built market that is implausibly high or implausibly low, either the customer count or the revenue-per-customer assumption is wrong, and the discrepancy localizes the error. Second, sensitivity-check revenue per customer across the triangulated range rather than a single point estimate, because in a niche with a handful of large accounts the mean and the median can tell different stories. Teams that keep this evidence source-linked throughout, as described in data provenance practice, can regenerate the reconciliation on demand instead of rebuilding it.
The recurring red flags are well documented in commercial diligence practice. Overstating the TAM by counting every dollar in an adjacent category may make a slide look impressive but rarely survives investor questioning; straight-lining growth from end-market CAGRs ignores real-world frictions of capacity, competition and channel dynamics; and treating SOM as a statement of ambition rather than a reflection of verified go-to-market reach inflates expectations and erodes credibility. Each of these is a sizing failure that a disciplined evidence checklist catches early, and each belongs on the risk register rather than in a footnote.
Transaction implications and workflow support
Sizing outcomes feed the deal directly. A verified TAM and SOM range anchors the growth assumptions in the operating model, which in turn frames the entry multiple the buyer can defend: paying a multiple that embeds top-decile growth is only rational if the counted market supports it. Where the build shows headroom the target has not yet reached, earn-out structures tied to market expansion become a way to bridge a valuation gap, and the census work identifies which add-on acquisitions would actually consolidate counted share rather than adjacent noise. Weak or unverified sizing does the opposite: it slows negotiation, invites re-trading, and hands the seller's advisers an easy target in the financial model discussions.
A diligence workspace supports this workflow without auto-sizing markets; the sizing judgment stays with the deal team, and the platform structures the evidence around it. Data Room Ingestion scans virtual data rooms and processes contracts, spreadsheets and financial models within minutes, so customer lists and pricing documents enter the analysis quickly. The AI-Analysis Engine reads and cross-references those documents, extracting and connecting the customer and revenue evidence that the unit build depends on, with source traceability on every finding. Risk Radar evaluates findings by materiality, financial impact and deal relevance, which is how an inflated TAM or an unsupported SOM assumption surfaces as a flagged risk rather than a buried assumption. Report Builder drafts the deliverable with every figure traced to its source, and a shared collaboration layer keeps the commercial, financial and legal workstreams aligned on the same evidence base. This is the working pattern for M&A advisory firms and fund teams alike: the machine organizes and accelerates the evidence, and the professionals size the market.
How to use this in your next diligence workflow
The method compresses into a sequence a deal team can run on a live transaction, and it maps cleanly onto a structured commercial due diligence checklist:
- Define the solution scope in writing: which products, use cases, buyer types and geographies are counted, and which are excluded.
- Count the addressable customer base from registries, NACE-code statistics and trade-association directories, filtered to the criteria that define a real buyer.
- Triangulate revenue per customer across contracts and pricing files, CRM exports and competitor rate cards, and disclose the spread rather than averaging it away.
- Constrain TAM to SAM and SOM using verified go-to-market reach, not ambition.
- Build the competitor census and quantify consolidation headroom against the sector enterprise count.
- Reconcile the build against the target's actual revenue and implied share, then sensitivity-check the revenue-per-customer range before the number reaches the investment committee.
The discipline that holds the sequence together is transparency about logic: practitioners who walk clients through every driver, unit and price input, from sources to confidence levels, produce market models that survive committee scrutiny because nothing in them is unverifiable. Plausity is built to make that transparency the default rather than an extra effort, connecting each sizing input to its source document across the whole workspace. Built for today's investment and deal teams. Trusted by >200 firms. On your next niche deal, the team that can show its units wins the argument, and the build above is how that showing is done.
How Plausity accelerates this workflow
Plausity is an AI-native due diligence and deal intelligence workspace that helps M&A advisory firms, VC and PE funds, corporate development teams and investment-banking teams structure evidence, findings and questions across a data room. Plausity supports evidence extraction, source grounding, findings management and IC preparation — it does not replace human analysts, advisers or investment professionals, does not provide legal, tax, audit, regulatory or investment advice, and does not make autonomous investment decisions. All findings require human review. Built for today's investment and deal teams. Trusted by >200 firms.
To explore the underlying capabilities, see the Plausity AI analysis engine and the findings and risk intelligence product page. For team-level workflows, see how VC and PE funds and M&A advisory firms use Plausity across live deals.


