Why disciplined shortlist screening matters now
Shortlist screening is the structured evaluation that ranks identified acquisition targets by strategic fit, financial profile and feasibility before confirmatory diligence costs mount. It is the discipline that turns a long list of identified companies into a defensible shortlist: every target is tested against the same criteria, on the same evidence, with explicit rules for when to stop. Once a target has been identified, the bottleneck is rarely sourcing. It is structuring: how quickly a corporate development team can organise the available evidence, compare candidates on comparable terms, and decide which ones deserve deeper diligence.
The market context sharpens the point. 63 deals valued above $10 billion were announced globally in 2025, and US M&A volume approached $2.3 trillion, a 49% increase on the prior year. Value is also concentrating at the top: one-third (33%) of total US deal value in 2025 was driven by only 20 very large transactions, which Deloitte reads as ample opportunity for prepared buyers and sellers in the small and middle markets. For a corporate development team, that means well-prepared, well-screened targets in the middle market attract multiple interested buyers, and the window between identification and a competitive process is short. That compression is why market analysis for an acquisition runs alongside the screen rather than after it.
The cost asymmetry is what makes screening discipline the cheapest risk filter in the deal lifecycle. Multiple studies suggest that 70-90% of acquisitions underperform expectations, and the failures trace back to identifiable mistakes in target selection, due diligence and synergy evaluation rather than bad luck. A structured screen consumes days of analyst time. A failed integration consumes years of management attention and, in documented cases, billions in write-downs. Screening is where that asymmetry is exploited: the earlier a weak target is stopped, the more diligence budget, negotiation leverage and management bandwidth remain for the targets that survive.
One definitional point anchors everything that follows. This article starts after identification: the target universe is mapped, the long list exists, and the question is no longer where to look but which identified target to advance. Screening is not sourcing, and no scorecard can rescue a universe that was never properly built. What screening can do, done well, is prevent the two classic shortlist failures: advancing a target because its narrative was compelling, and eliminating a strong one because its file was messier than a competitor's.
The shortlist workflow: a two-stage screening framework
The most reliable shortlist workflows are built as a stage-gate, not a single review. The purpose of the first gate is speed with discipline: a fast screen that eliminates targets which fail on fundamentals, so the team's analytical capacity concentrates on candidates that could genuinely clear the bar. The purpose of the second gate is depth: a focused desktop analysis of the survivors that produces a proceed-or-pause decision. For most shortlist decisions, a focused desktop analysis of roughly two weeks is enough to reach that decision; the point of the framework is not to delay diligence but to make sure confirmatory diligence is spent on targets that earned it.
Stage one: the fast screen
The fast screen fits on one page per target and tests three things. First, charter fit: does the target sit inside the acquisition strategy's defined segments, geographies and size range, or is it a compelling company that happens to be irrelevant to the thesis? Second, plausibility of the value thesis: can the team state in two sentences where the value comes from, and does the target's actual profile support that statement? Third, enterprise constraints: is there a plausible regulatory path, and does the target's scale, technology or organisational shape fit the acquirer's integration capacity? A target that fails any of the three is stopped here, with the reason logged.
Stage two: the deep screen on five dimensions
Survivors move to a deeper screen across the five evaluation dimensions practitioners consistently use. Each dimension is scored on defined criteria and weighted before the analysis begins, so the weights reflect strategy rather than whichever target has the most persuasive champion.
- Strategic fit or adjacency: capability uplift, customer or channel overlap, and how the target's position complements the acquirer's.
- Financial profile: revenue quality, margin structure, growth pattern and the plausibility of the financial picture behind the thesis.
- Concentration risk: dependence on a small number of customers, suppliers or contracts, and what happens to those relationships on a change of control.
- Regulatory and ESG exposure: antitrust path, sector-specific approvals, and environmental, social or governance liabilities that could delay or reprice the deal.
- Feasibility: seller readiness, realistic valuation range against the acquirer's return requirements, and integration load.
Two design choices determine whether the framework actually filters. The first is explicit kill criteria, agreed before files are opened: specific, observable conditions, such as a single customer above a defined revenue share or a valuation expectation far outside the return model, that stop a screen immediately rather than after three weeks of analysis. The second is scoring discipline: weights fixed in advance, scores documented with the evidence behind them, and a rule that any target advancing to confirmatory diligence carries a written thesis that the deep screen did not materially contradict. Teams that skip these choices tend to rediscover, at integration cost, what the screen was designed to surface in week one.
Evidence collection: what to request and how to structure it
At the shortlist stage, no data room has opened in earnest, and the evidence base is deliberately lighter than confirmatory diligence. The objective is comparability: every shortlisted target is evaluated against the same request pack, so differences in the ranking reflect differences in the businesses, not differences in how thoroughly each file was assembled. The standard request pack for the screen covers the following.
- Three years of historical financials plus trailing twelve months, on a consistent basis.
- Revenue by segment, product line or customer cohort, however the business actually splits.
- Top-customer analysis: revenue concentration, contract terms and renewal timing for the largest accounts.
- Headcount by function, including any material use of contractors.
- Capital expenditure history, split between maintenance and growth spend where available.
- A simplified cash flow view, to test whether reported earnings convert to cash.
- Tax footprint: entities, jurisdictions and any open audits or historical exposures.
- Key contracts: customer and supplier agreements with change-of-control or exclusivity clauses.
- Disclosure of disputes, litigation and contingent liabilities, however preliminary.
Structure this into a reusable template so the comparison is mechanical rather than narrative. Each target gets the same template: the same line items, the same definitions (what counts as recurring revenue, what counts as a top customer), and the same scoring fields that feed the strategic-fit scorecard described in the next section. A shared template also changes team behaviour. When the fields are fixed, analysts collect to the template instead of following whatever the target's management deck happens to emphasise, and the eventual side-by-side comparison rests on a common evidence base.
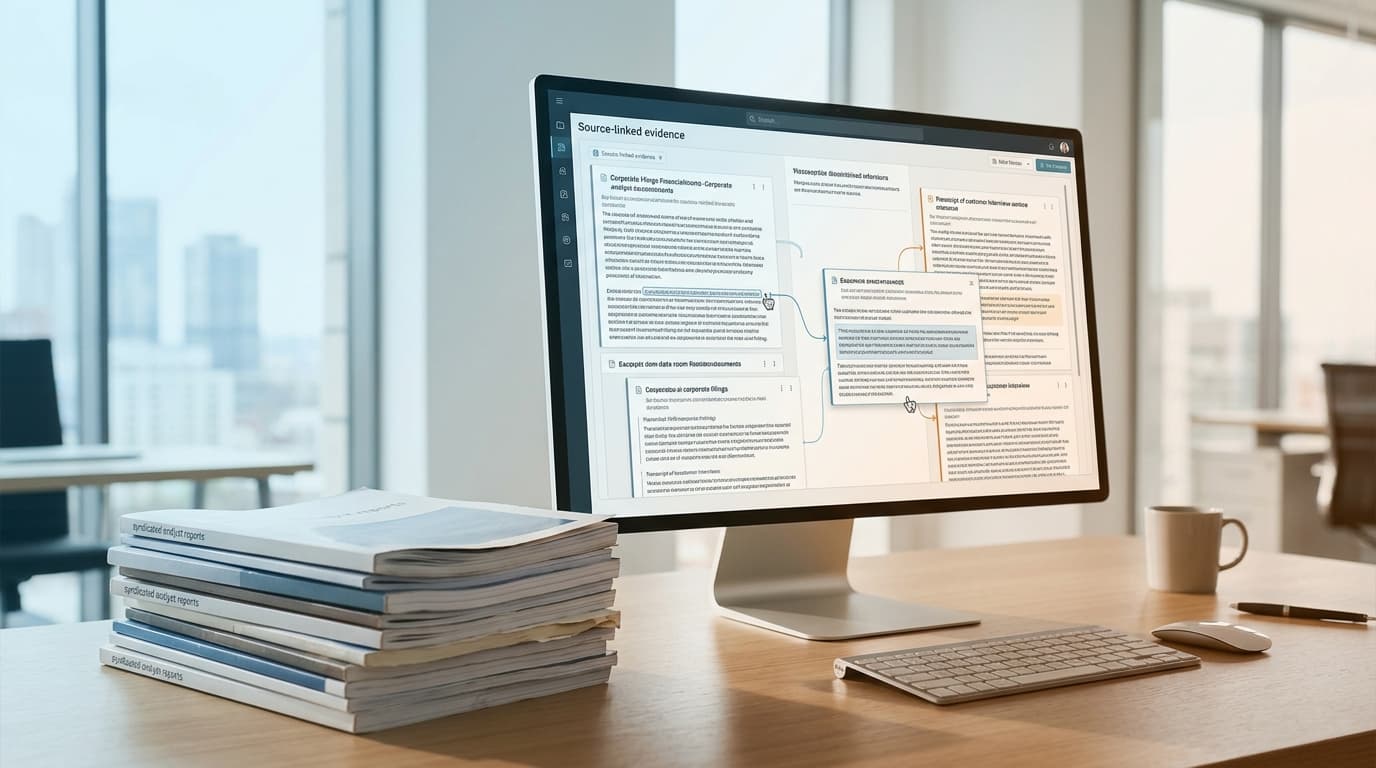
The third element is explicit evidence-gap tracking. At screening stage, some data will not exist, some will arrive late, and some will arrive in a form that does not answer the question. The discipline is to log every gap as a named item, with an owner and a plan for how confirmatory diligence will close it, rather than letting an assumption quietly fill the hole. An unlogged gap does not disappear; it becomes an unexamined assumption inside the thesis, and it is cheapest to surface while the team can still walk away. Teams using an AI-native analysis workspace can automate much of this: ingestion of whatever materials the target has shared, structured extraction against the template, and a running register of what is evidenced and what is not, for example through Data Room Ingestion applied to early-stage document sets.
Strategic-fit scorecards and comparable-target evaluation
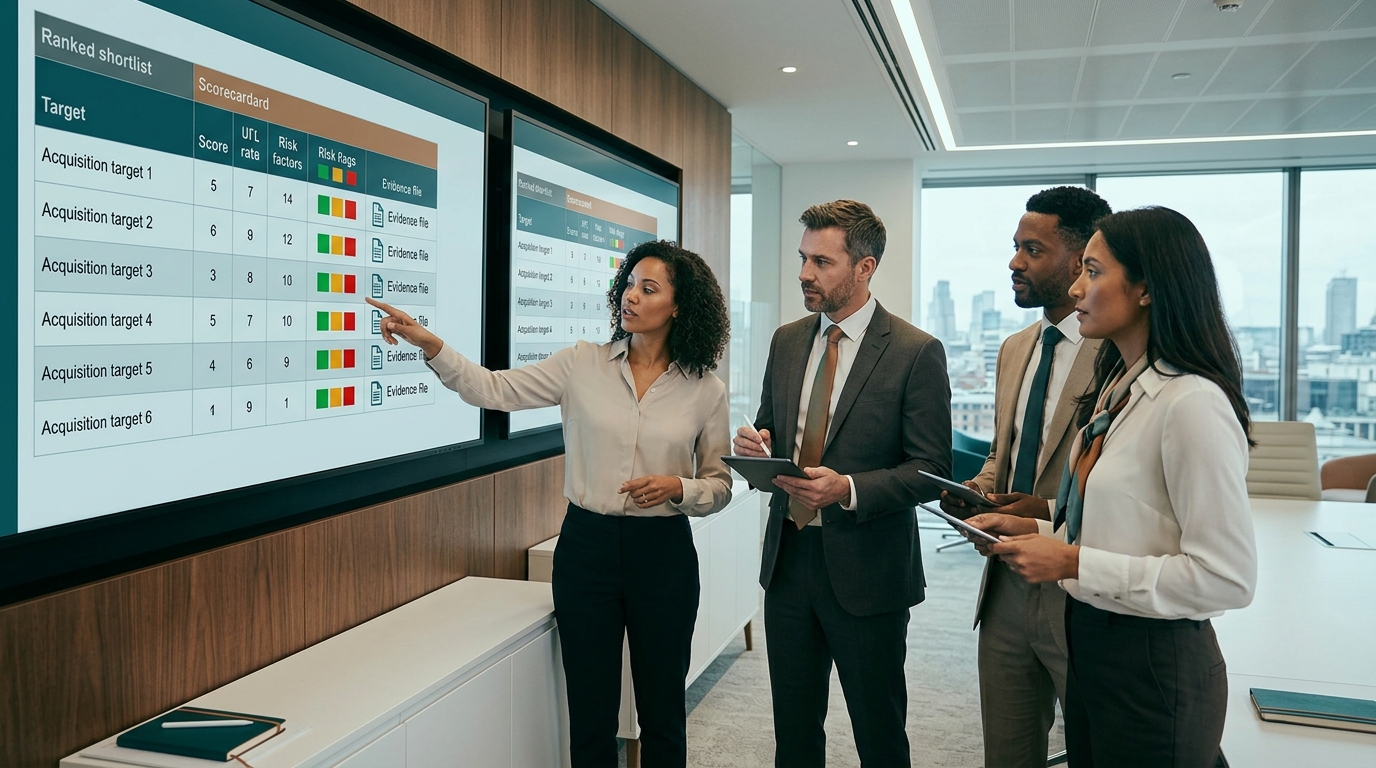
A weighted strategic-fit scorecard exists to remove narrative appeal from the ranking. The team defines a small set of fit criteria, agrees a weight for each before any target file is opened, and scores every shortlisted target on the same scale with the evidence attached to each score. The criteria that matter in most corporate acquisitions are capability uplift, channel or customer adjacency, technology complementarity, management depth, and synergy plausibility. Weights should come from the acquisition strategy, not from the deal champion: if speed to market is the thesis, adjacency and channel access outweigh technology depth; if the thesis is capability acquisition, the reverse holds.
Scorecard construction is straightforward; the discipline is in the sequencing. Weights are fixed before advocacy starts, scores are documented with sources, and any score that changes during the process changes with a recorded reason. This protects the screen from the most common distortion in corporate development: a target that acquires an internal sponsor early and is thereafter evaluated more generously than its peers. The scorecard also creates the audit trail that the investment committee or board will eventually ask for: why this target advanced and three others stopped, on what evidence, and who scored it.
Side-by-side comparison and the build-buy-partner test
With all targets scored on identical criteria, the shortlist becomes a side-by-side ranking rather than a set of separate impressions. Two tests sharpen it. The first is the build-versus-buy stress test: for each target, ask what the same strategic objective would cost through organic build or a partnership, how long each route takes, and whether the acquisition premium still clears the alternatives. A target that only wins because the comparison was never run is not yet a screened target. The second is the deal-type test: classify each candidate as a tuck-in, a growth platform or a consolidation play, and check that the classification matches where the value actually comes from. A tuck-in priced as a growth platform, or a consolidation play underwritten on synergy assumptions it cannot support, is a mismatch that the scorecard should catch before pricing does.
The output of this stage is a ranked shortlist with a defensible rationale per target: the weighted score, the evidence behind it, the deal-type classification, and the open questions that the next phase must answer. That package is what makes the eventual handoff to confirmatory diligence fast, and it is the standard against which the screening file should be judged.
Red flags and evidence gaps that stop a screen early
Some findings should not wait for confirmatory diligence. The purpose of listing red flags in advance is to remove discretion at the moment of discovery: when a screen surfaces one of these, the default response is to pause or stop, and continuing requires an explicit, documented decision to the contrary. The financial red flags that most reliably predict trouble are well understood.
- Unexplained step-changes in growth or margin that no management narrative reconciles with the underlying numbers.
- Revenue tied to a single customer, or to a contract approaching renewal, where change of control or competitive dynamics put the relationship at risk.
- Aggressive capitalisation of costs that flatters earnings and understates true operating expense.
- Deferred maintenance or sustained capex under-investment, which converts an earnings surplus into a post-close investment liability.
- Tax or VAT compliance issues, including structures that would not survive a change of ownership.
- Weak management depth below the founder or CEO, where the thesis depends on people who may not stay.
Commercial and people red flags deserve equal weight: customer churn that the financials smooth over, a sales pipeline concentrated in one geography or one product, key-person dependence in technology or commercial leadership, and cultural signals that surface in early management meetings. None of these is automatically disqualifying, but each one shifts the burden: the target must explain it with evidence, not with narrative.
The case for acting on them early is documented. Analyses of failed acquisitions repeatedly find that diligence warnings were visible but underweighted, and that many failures could have been averted if leadership had heeded them. Synergy overestimation in particular is among the most common causes of disappointing outcomes, with executives consistently overestimating synergies and underestimating cultural challenges. A screen that treats an unexplained margin step-change as a stop, rather than a detail to resolve after signing, is applying that lesson at the point where it costs least.
Escalation rules
Escalation should be procedural, not heroic. Three rules cover most situations. First, a red flag on a kill criterion stops the screen; only a documented decision by the deal owner restarts it. Second, a red flag that is not a kill criterion converts into a named diligence question with an owner, and the target does not advance until the question has a plan attached. Third, every red flag, resolved or not, transfers into the risk register that accompanies the target into confirmatory diligence, so nothing discovered during screening is rediscovered later as a surprise.
The handoff to confirmatory diligence
Confirmatory due diligence begins after a letter of intent, when the buyer verifies every assumption built during screening against full data room access. The quality of the screening file therefore determines how fast and how clean that phase runs. A screening file built on a shared template, a fixed scorecard and an explicit gap register hands the diligence team a starting position: they know what has been evidenced, what has been assumed, and which questions are already open. A screening file built on scattered notes and remembered conversations hands them a rebuild.
What a clean handoff contains
- The completed strategic-fit scorecard, with weights, scores and the evidence behind each score.
- The evidence file: every document collected during screening, indexed against the standard template.
- The open questions: every logged evidence gap, converted into a diligence request or hypothesis to test.
- The risk register: every red flag from the screen, with its status and the escalation decision taken.
With those four artefacts in place, workstream allocation becomes a mechanical step: financial, commercial, legal due diligence, technology and operational workstreams each inherit the questions that belong to them, and confirmatory diligence starts from hypotheses rather than from a blank request list. This is the workflow that structured diligence platforms are built around; for a view of how the same evidence discipline applies across fund and advisory teams, see the workspace for VC & PE funds and for M&A advisory firms.
Where the analysis workspace fits
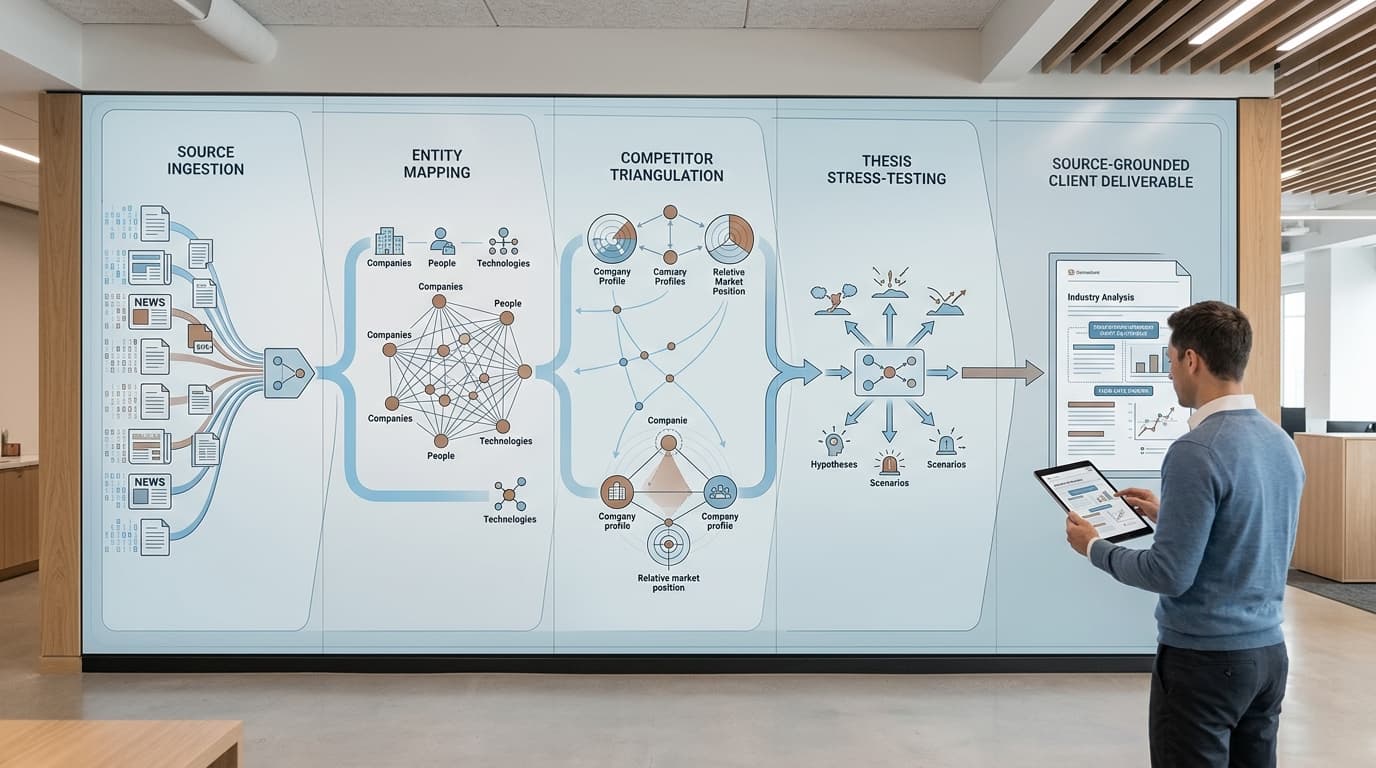
Plausity is an AI-native due diligence and deal intelligence workspace, and its role in this workflow begins once a target is on the shortlist; it is not a target-sourcing database. Once a data room opens, Data Room Ingestion connects to and scans virtual data room contents, ingesting PDFs, spreadsheets, contracts and financial models within minutes. The AI Analysis Engine then reads and cross-references those documents to structure findings with source traceability, so each finding points back to the document it came from. Findings and risk intelligence evaluates those findings by materiality, financial impact, legal exposure and deal relevance, which is how the red flags from the screen get tested against full data room evidence rather than early-stage materials. Collaboration and workflow coordinates the workstreams, task assignment and expert review that confirmatory diligence requires, and reports and deliverables drafts investor-ready outputs with the same source traceability, so the final report inherits its evidence from the analysis rather than being assembled after it. Built for today's investment and deal teams. Trusted by >200 firms.
How to use this in your next diligence workflow
The framework above compresses into a sequence a corporate development team can run on its current shortlist without changing headcount or tooling. The steps are tool-agnostic; an analysis workspace accelerates each one, but none of them depends on it.
- Fix the criteria and weights before opening target files. Write down the five dimensions, their weights and the kill criteria, and get the deal owner to sign them off before any target narrative is heard.
- Run the fast screen with explicit kill criteria. One page per target: charter fit, thesis plausibility, enterprise constraints. Stop the failures here and log the reason.
- Collect evidence against the standard template. Issue the same request pack to every surviving target and record what arrives, in what form, against the same line items.
- Score all targets on the same scorecard. Weights fixed, scores documented with sources, deal type classified, and the build-buy-partner test run for each candidate.
- Log every evidence gap as a diligence question. No assumption fills a hole silently; each gap gets an owner and a plan.
- Hand the survivors to confirmatory diligence with a complete screening file: scorecard, evidence file, open questions and risk register, so the post-LOI phase starts from hypotheses rather than from scratch.
How Plausity accelerates this workflow
Plausity is an AI-native due diligence and deal intelligence workspace that helps M&A advisory firms, VC and PE funds, corporate development teams and investment-banking teams structure evidence, findings and questions across a data room. Plausity supports evidence extraction, source grounding, findings management and IC preparation — it does not replace human analysts, advisers or investment professionals, does not provide legal, tax, audit, regulatory or investment advice, and does not make autonomous investment decisions. All findings require human review. Built for today's investment and deal teams. Trusted by >200 firms.
To explore the underlying capabilities, see the Plausity AI analysis engine and the findings and risk intelligence product page. For team-level workflows, see how VC and PE funds and M&A advisory firms use Plausity across live deals.